Inicio > > Bases de datos > Diseño y teoría de bases de datos > Big Data Analytics with Hadoop and Spark
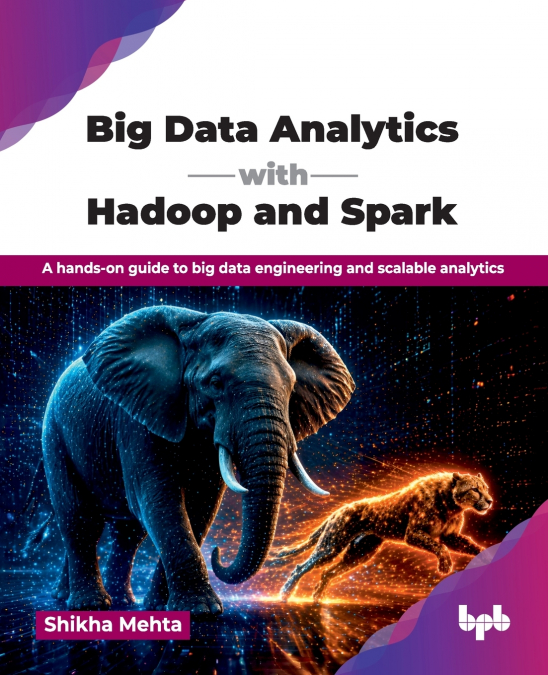
Big Data Analytics with Hadoop and Spark

Big Data Analytics with Hadoop and Spark

Shikha Mehta

50,39 €
IVA incluido
Disponible
Editorial:
BPB Publications
Año de edición:
2026
Materia
Diseño y teoría de bases de datos
ISBN:
9789365894745
50,39 €
IVA incluido
Disponible
Añadir a favoritos

Technologies like Hadoop and Spark, powered by the Cloudera platform, have become essential for storing, processing, and analyzing big data across various industries, including finance, healthcare, e-commerce, and research in today’s data-driven world.This book systematically navigates the entire ecosystem, starting with big data fundamentals, security, and HDFS architecture before mastering MapReduce through weather and stock data case studies. Readers will gain hands-on experience with the Cloudera framework, learning high-level scripting with Pig Latin and structured data warehousing using HiveQL’s Metastore and partitions. Additionally, it explores NoSQL versatility with HBase and MongoDB’s CAP theorem, followed by Scala programming and Spark’s high-speed in-memory engine. You will learn to optimize queries with the Catalyst optimizer and process complex Parquet or JSON files using Spark SQL DataFrames. The book also covers machine learning pipelines with spark.ml for professional-grade classification and clustering applications.By the end of this book, readers will be able to develop strong conceptual clarity and practical expertise in big data analytics. This will enable them to confidently design, implement, and manage scalable data processing solutions, preparing them to solve real-world data challenges and take on professional roles in big data engineering and analytics.WHAT YOU WILL LEARN● Understand big data concepts, architecture, ethics, and applications.● Build scalable storage using HDFS and MapReduce.● Perform data analysis using Pig and Hive.● Develop NoSQL solutions using HBase and MongoDB.● Process large datasets using Apache Spark.● Analyze data using Spark SQL and DataFrames.● Implement machine learning using PySpark.WHO THIS BOOK IS FORThis book is ideal for students, researchers, and academicians. It empowers aspiring big data engineers, data scientists, and software engineers. Readers should possess basic programming knowledge and database fundamentals to master Hadoop and Spark for professional-grade data science and faculty-level instruction.
Artículos relacionados

  • Exploring Advances in Interdisciplinary Data Mining and Analytics
    Data mining is still a relatively young field, expanding at the rate of technology while advancing tools and techniques for gaining knowledge, finding patterns, and managing databases. Exploring Advances in Interdisciplinary Data Mining and Analytics: New Trends is an updated look at the state of technology in the field of data mining and analytics. As processor speeds, databas...
  • Knowledge Discovery Practices and Emerging Applications of Data Mining
    Recent developments have drastically increased the volume and complexity of data available to be mined, leading researchers to explore new ways to glean non-trivial data automatically. Knowledge Discovery Practices and Emerging Applications of Data Mining: Trends and New Domains introduces the reader to recent research activities in the field of data mining. This book covers as...
  • Research and Trends in Data Mining Technologies and Applications
    David Taniar
    ...
  • Developing Metadata Application Profiles
    The prevalence of data science has grown exponentially in recent years. Increases in data exchange have created the need for standards and formats on handling data from different sources. Developing Metadata Application Profiles is an innovative reference source that discusses the latest trends and techniques for effectively managing and exchanging metadata. Including a range o...
  • Modern Technologies for Big Data Classification and Clustering
    Data has increased due to the growing use of web applications and communication devices. It is necessary to develop new techniques of managing data in order to ensure adequate usage. Modern Technologies for Big Data Classification and Clustering is an essential reference source for the latest scholarly research on handling large data sets with conventional data mining and provi...
  • 90 Gelöste Fälle zu Zeitintelligenz in der DAX-Sprache
    Ramón Javier Castro Amador
    Dieser Ratgeber ist rein praktisch ausgerichtet, so dass Sie den gesamten DAX-Code in dieser Publikation anhand einer zum Download verfügbaren .pbix-Datei testen können.'90 gelöste Fälle zu Zeitintelligenz in DAX' ist ein Ratgeber für Benutzer von Microsoft Power BI, der Lösungen für sehr häufige praktische Fälle in Zeitintelligenzmodellen in der Sprache DAX bietet.Um das Verst...
    Disponible

    16,15 €